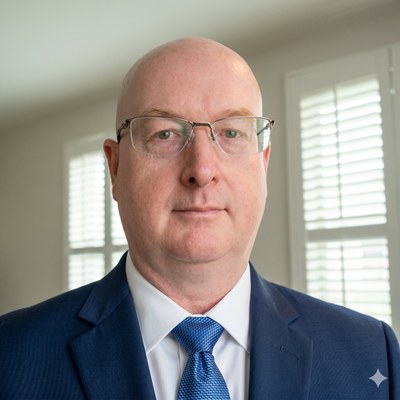
About Kevin Walsh
Kevin Walsh leads Brainpan.AI’s work across generative engine optimization, answer engine optimization, AI citation optimization, schema implementation, and share-of-model measurement. His work focuses on helping brands become clearer, more extractable, and more credible to AI answer systems.
Brainpan.AI’s methodology combines technical SEO, structured data, content architecture, entity clarity, and competitive citation intelligence into a practical operating system for AI visibility.
He came to the problem from the measurement side. Before founding Brainpan.AI, Kevin spent more than fifteen years in enterprise B2B search and data strategy, including a period as Director of Member Insights & Data Sciences at AARP, where the work was building the analytics that told a national membership organization what its audience actually did rather than what it said it would do. He holds an MBA from HEC Paris.
That background shapes how Brainpan.AI approaches AI visibility. The shift from ranked links to synthesized answers broke the measurement layer before it broke the marketing layer: rank tracking still reports a number, but the number no longer describes what a buyer sees when they ask ChatGPT, Gemini, Perplexity, Copilot, or Claude which vendors to consider. Kevin’s position is that a brand cannot manage a surface it has never measured, which is why every engagement starts with a citation baseline rather than a recommendations deck.
The published research follows from the same position. Brainpan.AI publishes its own benchmark research so the measurement claims are testable by anyone: the Q2 2026 AIVI™ Insurance Benchmark scored 134 insurance brands across 300 stratified prompts and 1,500 model responses on five engines, and the Q3 2026 Medicare AIVI™ Benchmark tracked 121 Medicare brands across seven AI surfaces. Top-10 results are published as open JSON under CC BY 4.0; the full 134-brand index is available under a commercial license.
Published research
Kevin authors and maintains the Brainpan.AI research program. Each edition is versioned, organic-only, and reproducible from the published method rather than from a proprietary black box.
- AIVI™ Insurance Benchmark, Q2 2026: named rankings across ChatGPT, Gemini, Perplexity, Copilot, and Claude, with per-brand records for the published top ten exposed as open JSON.
- AIVI™ Methodology and Correction Policy v1.0 — prompt-set construction, attribution rules, the five weighted components, the stated limitations, and a formal process for any named organization to challenge a published figure.
- The Hartford AI Visibility Analysis — a worked diagnostic showing how a brand can hold the highest top-three rate in the published top ten (88.1%), with the lowest recommendation rate in the top ten (27.6%), and still rank eighth on the composite index.
- Allstate AI Visibility Analysis — the mirror case: the third-highest share of model in the study, sixth on the composite, and the recommendation mix that decided a margin of 6.72 Visibility Points.
- Nationwide AI Visibility Analysis — the efficiency case: the worst placement in the published top ten, the best citation rate in it, and fifth overall.
- Medicare AIVI™ Benchmark, Q3 2026: 121 tracked Medicare brands across seven AI surfaces (ChatGPT, Gemini, Claude and Perplexity through their APIs; Google AI Overviews, Microsoft Copilot and Bing Copilot), with reach and per-mention quality (QVI™) reported separately.
- Medicare AIVI™ Methodology and Correction Policy v1.0: study design, the QVI™ formula, attribution rules, known limitations and the correction record.
- UnitedHealthcare Medicare AI Visibility Analysis: the commercial-share leader (18.35%) ranks ninth on QVI™ and second-to-last in the published head-to-head table.
- Kaiser Permanente Medicare AI Visibility Analysis: 2.47% of commercial mentions, 17 wins in 20 scored head-to-head appearances, and a 0.1% own-domain citation rate.
The operating frameworks
The consulting work is documented rather than improvised. Four published Brainpan.AI frameworks carry it: AI Retrieval Optimization is the content-layer standard for making prose parseable and extractable; AI Visibility Infrastructure is the technical and semantic foundation — schema deployment, entity disambiguation, and Knowledge Graph accuracy; the AI Visibility Protocol is the pre-publish standard that makes new content citation-ready the day it goes live; and the AI Visibility OS is the monthly cadence, workflow, and measurement loop that runs the other three.
How engagements work
Every engagement starts with an AI Visibility Audit: a citation baseline across up to eight AI platforms, a competitive gap map, and a prioritized roadmap. From there the work splits into implementation — a Schema Implementation Sprint or AI Citation Optimization — and measurement, through monthly citation reporting that tracks share of model month over month and reports it in a form a CMO can take to a board. Kevin runs the audit and the strategy directly; there is no account layer between the client and the person doing the analysis.
Areas of expertise
- AI Visibility Infrastructure: building the content, schema, and entity systems that help brands become retrievable and citable in AI-generated answers.
- GEO and AEO Strategy: mapping the query categories, answer formats, and semantic structures that influence AI and answer-engine selection.
- Schema and Structured Data: creating Organization, Person, Service, Article, FAQPage, WebPage, BreadcrumbList, and related JSON-LD systems for extraction readiness.
- Share-of-Model Measurement: benchmarking citation presence across ChatGPT, Gemini, Perplexity, Copilot, Claude, and AI-powered search systems.